No. Private AI can be appropriate. However, proprietary information alone does not tell you where the AI system should run.
It tells you that the decision must be deliberate.
A managed business product may meet your requirements. A model hosted inside your cloud environment may be a better fit. A self-hosted or on-premises system may fit when information cannot cross a defined boundary. It may also fit when the company needs deeper control or a managed service cannot meet an operating requirement.
The mistake is starting with “we need our own model.” Instead, define what needs protection and how the complete system will use the information.
“Not used for training” is only one question
Several commercial AI offerings state that business inputs and outputs are not used to train their models by default. For example, OpenAI's current business-data commitments cover named business products and the API platform. Similarly, Anthropic says it does not use chats or coding sessions from its commercial offerings for training. The stated exceptions involve explicit participation or opt-in.
Those commitments matter. They do not answer the entire deployment question.
You still need to know:
- which exact product, plan and account will process the information;
- where processing and storage occur;
- what is retained, for how long and for which purpose;
- whether a chosen feature creates stored conversations, files, vector stores or logs;
- who can administer or retrieve that data;
- which connectors, tools and downstream systems receive it;
- what happens when content is flagged for abuse or safety review;
- whether the configuration and contract meet your organization's actual requirements.
Retention can also vary by plan, feature and model. For example, Anthropic documents custom retention controls for Claude Enterprise. It also describes separate conditions for certain models and zero-data-retention arrangements. Therefore, read the terms for what you will actually buy.
First define the information boundary
Before comparing vendors or hardware, make a small data-flow map.
| Question | Decision to record |
|---|---|
| What information enters the system? | Documents, database fields, messages, code, images or other sources |
| How is it classified? | Public, internal, confidential, client-restricted, regulated or another company-defined category |
| What does the model receive? | Full record, selected fields, redacted text, retrieved passages or a derived summary |
| What else touches it? | Ingestion service, storage, retrieval index, monitoring, logs, backups, support tools and external APIs |
| Where may it be processed and stored? | Approved providers, accounts, regions, networks and physical locations |
| Who may access it? | Users, administrators, implementation team and support personnel |
| How long may each copy remain? | Source, prompt, response, application history, telemetry, backup and error record |
| What action can the AI take? | Read-only answer, draft, database update, external message or another bounded operation |
This often reveals that the model is only one part of the privacy boundary. Running a model on your own server does little if the application sends traces to an unapproved monitoring service. The same problem appears when prompts enter a broadly accessible database or every user receives identical retrieval permissions.
Compare three practical private AI deployment patterns
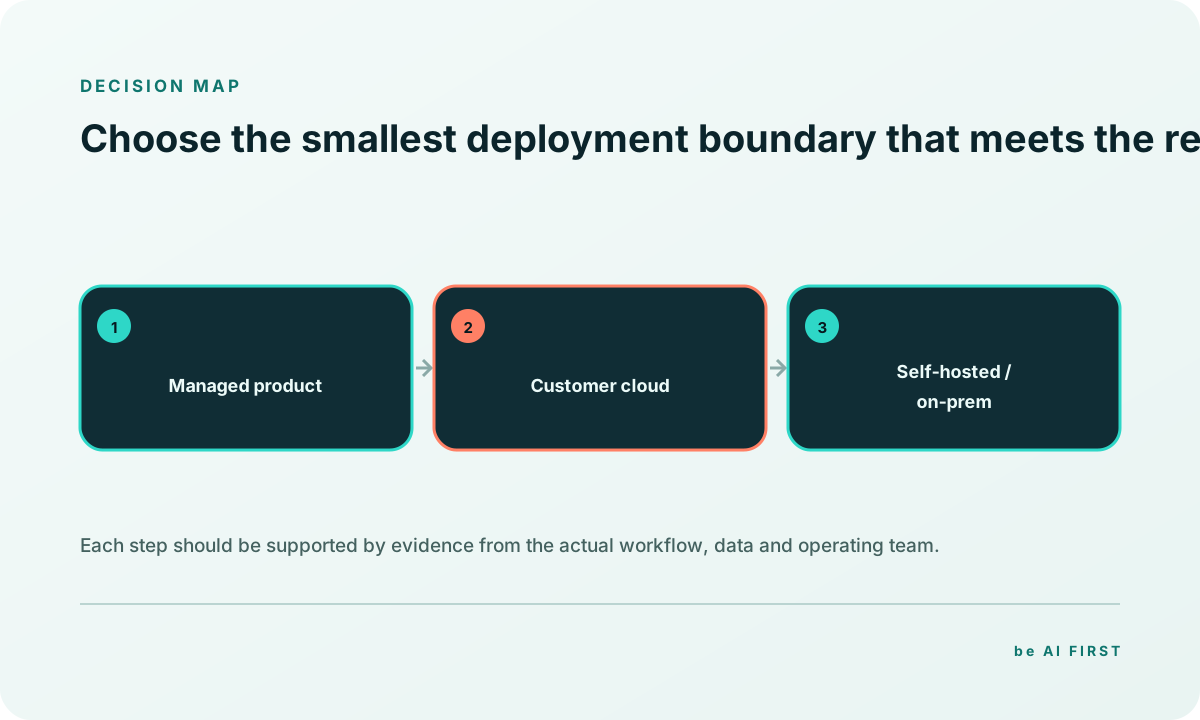
1. Managed business product or API
This often provides the fastest route when the provider's business terms, controls and integrations meet the requirement.
It can fit when:
- the organization permits the provider to process the relevant data;
- the required retention, access and geographic controls are available;
- the application does not need deep infrastructure customization;
- speed, model capability and lower operating burden matter more than direct control of the model runtime.
Verify the exact product. Consumer, business, enterprise and API offerings can have different terms and controls. Also verify optional features. A tool that stores conversation history or uploaded files may behave differently from a stateless inference request.
2. Model service inside your cloud environment
This can align with existing cloud identity, networking, logging and data-residency architecture. Meanwhile, the provider continues to operate the model-serving infrastructure.
For example, Microsoft's current Foundry data and privacy documentation addresses prompts, completions and training data. It says Microsoft does not use them to train foundation models without permission. It also explains that storage and processing vary by feature and deployment type. That second part is equally important.
This pattern can fit when:
- business data already resides in the cloud environment;
- the company wants existing identity, network and governance controls to apply;
- a managed model service meets the required capability;
- the organization accepts the cloud provider and documented service boundary.
It is still a third-party managed service. Therefore, check the service documentation, support model and configuration before drawing conclusions about who may process information.
3. Self-hosted, private-cloud or on-premises AI
This pattern may fit when the model and supporting components must stay inside a controlled boundary. It may also fit offline operation or a specific data-sovereignty requirement. Finally, it may provide model and runtime control that managed offerings cannot provide.
It adds responsibilities:
- selecting and licensing the model;
- provisioning capacity for normal and peak demand;
- securing the runtime and supply chain;
- evaluating model quality for the actual task;
- patching, monitoring and incident response;
- managing retrieval, logs, backups and access;
- planning upgrades or model replacement;
- paying for idle capacity and the people who operate it.
Self-hosting can increase control. It does not automatically make the whole application private, compliant, cheaper or reliable. Our guide to private and open-weight AI covers model licensing and ownership-cost questions in more detail.
Use requirements to choose, not fear or fashion
The following signals help narrow the decision.
| Requirement | Direction to investigate | What still needs proof |
|---|---|---|
| Standard internal productivity with approved business data | Managed business product | Product-level terms, settings, identity, retention and connector access |
| Application integration with controlled usage | Managed API or cloud model service | Data flow, storage features, authentication, monitoring and cost per completed task |
| Data must remain inside a customer-controlled cloud boundary | Customer-controlled cloud architecture | The documented service boundary, region behavior and every connected component |
| Disconnected or facility-only operation is mandatory | On-premises or edge deployment | Required capability on available hardware, maintenance and recovery |
| Mixed sensitivity across tasks | Split or hybrid design | Reliable classification and routing that cannot silently cross the boundary |
| High and steady inference volume | Compare managed and self-hosted economics | Utilization, quality, peak capacity, staffing and lifecycle costs |
| Need to customize answers using company knowledge | Retrieval may be sufficient | Source permissions, retrieval quality and whether fine-tuning is actually necessary |
These are directions for investigation, not automatic answers. The responsible legal or business leaders should interpret legal, contractual and sector-specific requirements. Then the technical team should prove that the implementation meets the approved requirement.
Test the entire route with representative data
Before production use, verify the deployed system rather than the architecture diagram.
- Send a representative but appropriately approved test record through the complete flow.
- Confirm what reaches the model and what is removed or transformed first.
- Inspect application storage, model-service features, logs, monitoring and backups.
- Test a user who should have access and one who should not.
- Trigger an error and determine what data appears in diagnostics and support workflows.
- Confirm deletion and retention behavior where the requirement calls for it.
- Record the configuration, account owner and evidence so the test can be repeated after a material change.
Do not use confidential production information merely to prove the design. Start with approved test data. In addition, involve the people responsible for security, privacy, operations and the business process in the acceptance decision.
The lowest-risk system may be the simpler one
A highly customized private deployment can satisfy a real requirement. However, it can introduce unnecessary infrastructure or a weaker model for the task. It can also create more access risks and an operating burden the company cannot support.
Conversely, selecting a familiar managed tool without examining its exact data flow can leave important requirements unanswered.
The aim is not to maximize privacy language or infrastructure ownership. It is to choose the simplest implementation that meets the documented information, capability, cost and operating requirements.
If you are comparing these options, explore our private AI deployment service. Bring a high-level description of the information, its required boundary and the task the system must perform. However, do not send confidential records or credentials for an introductory conversation.